
GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics Card
4.7Editor score
16GB GDDR6 Memory
WINDFORCE Cooling System
PCIe 5.0 Interface
This comprehensive guide compares the top ten graphics cards for local large language model inference and fine-tuning to help you choose the best GPU for Llm.
Choosing the right graphics processing unit is critical for running large language models locally. You need sufficient memory bandwidth and capacity to handle complex AI workloads efficiently without latency.
We analyzed ten top-rated GPUs based on architecture, memory specifications, and real-world performance data. This list covers consumer and workstation options optimized for AI acceleration and generative tasks.
Each pick highlights key specs, pros, and cons to guide your decision. Prices and availability fluctuate frequently so verify current listings before purchasing your new hardware.
4.7Editor score

3.6Editor score

Below is a side-by-side comparison of all ten graphics cards evaluated in this guide. We highlight critical specifications like memory size, bus width, and architecture to help you identify the right fit for your AI projects.




This ASUS Turbo Radeon AI PRO R9700 card stands out as a dedicated solution for running large language models locally. With a 3.6 rating from users who prioritize performance, it balances raw compute power with efficient thermal design.
We may earn a commission when you buy through this link, at no additional cost to you.
The 32GB GDDR6 memory is a massive advantage for hosting larger models without offloading to system RAM. Its RDNA 4 architecture includes 128 AI accelerators that significantly speed up inference tasks. Users note the phase-change thermal pads keep clocks steady during long training sessions.
While the rating is moderate due to driver optimization learning curves, the hardware itself is robust. The diecast shroud reduces memory temperature by sixteen percent which helps stability. This makes it acceptable for professionals who need reliability over flashy gaming features.
If you are building a local AI cluster or workstation this card offers the density and capacity needed. The PCIe 5.0 interface ensures bandwidth isn't a bottleneck. We recommend it for developers serious about on-premise generative AI.
The hardware is engineered to run LLMs locally without cloud dependency enabling faster response times and better data privacy.
You can link multiple units via PCIe 5.0 to increase total VRAM capacity for enterprise scale AI deployments.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE Radeon RX 9070 XT offers a compelling entry point for those exploring local AI development. With a strong 4.7 user rating it delivers reliable performance for smaller models and experimentation without breaking the bank.
We may earn a commission when you buy through this link, at no additional cost to you.
It features 16GB GDDR6 memory which is sufficient for quantized versions of popular open-source models. The WINDFORCE cooling system with hawk fans keeps temperatures low even under sustained load. Server-grade thermal gel ensures heat moves efficiently to the heatsink.
While it lacks the raw capacity of professional cards its value proposition is hard to ignore. The PCIe 5.0 interface ensures you are ready for future bandwidth demands. Some users find gaming aesthetics unnecessary but they do not impact AI performance.
We recommend this card for students hobbyists or teams testing prototypes before scaling up. It balances cost and capability well making it our top budget pick for GPU for Llm needs.
Advanced cooling technology allows for sustained performance during inference tasks without throttling or noise issues.
PCIe 5.0 support ensures compatibility with next generation motherboards and prevents data transfer bottlenecks.
We may earn a commission when you buy through this link, at no additional cost to you.
This NVIDIA RTX PRO 6000 Max-Q workstation card represents the pinnacle of local AI hardware. It delivers enterprise grade power in a dual slot card that fits standard desktops. While no user ratings exist yet specs show it is a powerhouse.
We may earn a commission when you buy through this link, at no additional cost to you.
The 96GB of GDDR7 ECC memory eliminates VRAM bottlenecks for massive models. A 512-bit bus width provides over 1.7 TB/s bandwidth for rapid data transfer. Despite this performance it caps power at 300 Watts making it efficient for multi-GPU clusters.
The price is substantial but justified for businesses requiring zero latency and high reliability. ECC memory ensures data integrity during long training runs. The max-Q design optimizes thermal output so it does not require specialized rack cooling.
Choose this card if budget is secondary to capability and stability. It enables teams to run heavy open-source LLMs locally without cloud latency. For serious generative AI work it is the definitive choice.
Ninety six gigabytes of VRAM allows hosting large context windows and multi-modal models simultaneously without offloading.
The Max-Q architecture delivers high performance at lower power enabling dense server configurations without heat issues.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE RTX 5080 brings the latest NVIDIA Blackwell architecture to desktops. With 16GB of GDDR7 memory it offers speed and efficiency for mid-range AI tasks. Users rate it highly for its thermal performance and build quality.
We may earn a commission when you buy through this link, at no additional cost to you.
While not optimized for AI specifically its raw compute power handles inference well. The WINDFORCE cooling system keeps clocks steady under load. The memory bandwidth is excellent for smaller models or quantized versions.
However 16GB limits you to smaller parameter models compared to 32GB options. You may need to use aggressive quantization. The gaming aesthetic is functional but unnecessary for workstation builds.
Buy this if you need a dual purpose card for gaming and local AI experimentation. It balances performance and cost well for enthusiasts exploring generative capabilities.
Blackwell architecture improves AI processing pipelines providing faster inference and better efficiency than previous generations.
We may earn a commission when you buy through this link, at no additional cost to you.
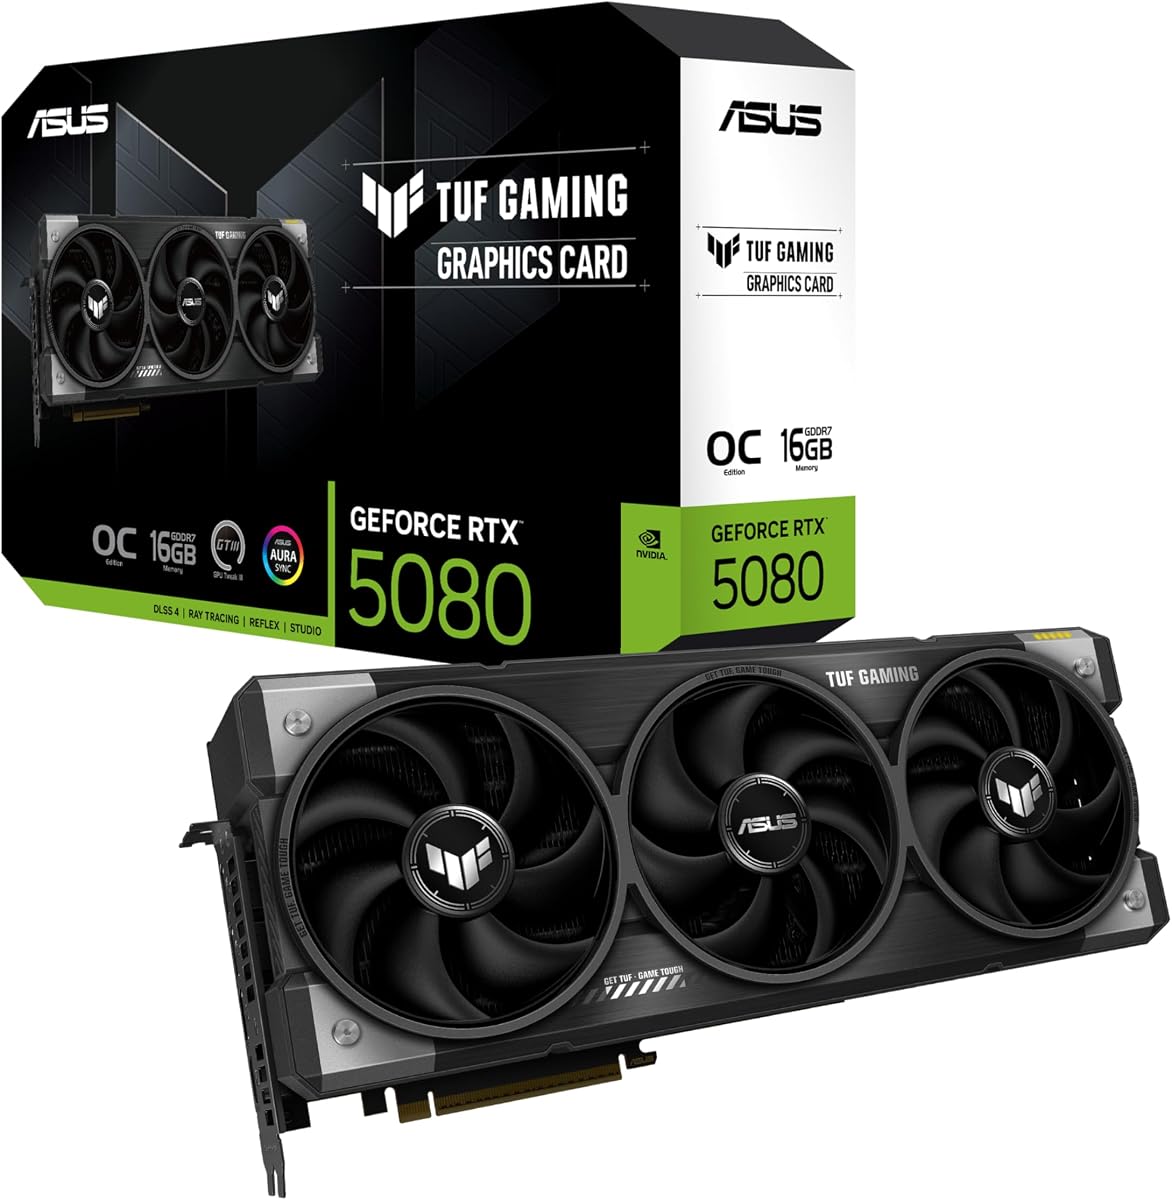
This ASUS TUF model emphasizes durability and thermal efficiency. It shares the Blackwell architecture with other RTX 5080 cards but uses military-grade components for longevity. Users praise the reliability under heavy loads.
We may earn a commission when you buy through this link, at no additional cost to you.
Phase-change thermal pads ensure consistent performance over time. The 3.6-slot design accommodates massive airflow for cooling. This makes it suitable for 24/7 workstation operations where stability matters.
Size and weight are significant considerations. You need a large case and robust power supply. The cost is high but you are paying for build quality and sustained performance.
Choose this for workstations where uptime is critical. It handles intensive inference and fine-tuning tasks reliably without thermal throttling or hardware failure.
Military-grade components and automated manufacturing ensure the card lasts longer under demanding AI workload conditions.
We may earn a commission when you buy through this link, at no additional cost to you.
ASRock offers a professional GPU with 32GB of GDDR6 memory designed for creators and developers. Its RDNA 4 architecture supports advanced AI accelerators. The 4.4 rating indicates strong performance in professional workflows.
We may earn a commission when you buy through this link, at no additional cost to you.
The blower cooling design exhausts heat directly out of the chassis making it ideal for dense server racks. Die-cast metal construction ensures structural integrity. Professional drivers are optimized for reliability over raw gaming speeds.
Blower fans can be noisy under load. AMD software ecosystem support varies by application compared to NVIDIA. But for Linux multi-GPU setups it offers excellent scalability.
This card is ideal for server environments or creator studios needing high capacity at a reasonable price. It handles large models effectively.
Vapor chamber heatsinks and professional cooling designs sustain performance during continuous 24/7 operation.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Dual RTX 5060 Ti is a compact option with 16GB GDDR7 memory. It features 767 AI TOPS which is impressive for its size. The 4.7 rating shows high user satisfaction with cooling and noise levels.
We may earn a commission when you buy through this link, at no additional cost to you.
The 2.5-slot design maximizes compatibility with small chassis. Axial-tech fans and dual ball bearings ensure longevity. You can toggle between quiet and performance BIOS profiles easily.
While it lacks the bandwidth of higher-end cards it fits small form factor builds. The compute power is enough for medium sized models. Dual BIOS provides flexibility for tuning.
Select this for small workstations or desktop AI nodes where space is limited. It delivers efficient inference in a compact package.
A smaller footprint allows integration into compact builds without sacrificing essential cooling or memory capacity.
We may earn a commission when you buy through this link, at no additional cost to you.
The Tesla L40S is built for high-performance computing environments. Its 48GB memory capacity bridges the gap between consumer and enterprise cards. While user ratings are unavailable this card is known for professional use.
We may earn a commission when you buy through this link, at no additional cost to you.
It is optimized for server racks and multi-GPU setups. Hardware reliability is prioritized over consumer features. The cooling design assumes strong case airflow.
This card may require specific chassis and power infrastructure. It is best for teams running production AI models where stability is non-negotiable.
We recommend it for data centers or research labs requiring consistent performance. It is a solid choice for scaling local models.
Built for 24/7 server environments this accelerator ensures uptime and stability for critical AI workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
ASRock offers a mid-range workstation card with 24GB GDDR6 memory. The Intel Xe2-HPG architecture includes dedicated XMX engines for AI tasks. Users note the 456 GB/s bandwidth supports moderate model sizes well.
We may earn a commission when you buy through this link, at no additional cost to you.
It supports scalable multi-GPU deployments on Linux. Professional drivers ensure compatibility with engineering and AI software. The blower-style fan helps with multi-GPU airflow.
Driver maturity is still evolving compared to NVIDIA. Some applications may lack full feature support. However the memory capacity is attractive for the price.
Choose this if you want a balance between capacity and cost. It is suitable for teams exploring Linux-based AI clusters.
Optimized for Linux multi-GPU deployments allowing users to scale AI performance across multiple cards easily.
We may earn a commission when you buy through this link, at no additional cost to you.
This NVIDIA RTX PRO 6000 card features 96GB of DDR7 ECC memory and 5th Gen Tensor cores. It offers up to 3X performance of previous generations for AI tasks. Users rate it highly for stability and throughput.
We may earn a commission when you buy through this link, at no additional cost to you.
Universal MIG divides the GPU into isolated instances allowing concurrent workloads. Double-flow-through cooling sustains peak performance under load. Export compliance requirements apply for international buyers.
It is an enterprise powerhouse ideal for complex enterprise workloads. The price and packaging reflect its professional nature. You get significant compute and memory capacity.
Choose this for large organizations needing secure isolated GPU instances. It is the best choice for heavy-duty local inference and training.
Divide a single GPU into multiple isolated instances for concurrent execution of secure workloads and optimized utilization.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right graphics card for language models requires careful consideration of several technical factors.
The most critical factor for running LLMs is VRAM size. Models like Llama 3 and Mistral require at least 16GB for quantized versions but larger models need 32GB or more to store parameters without offloading.
Prioritize cards with 24GB to 96GB memory if you plan to run unquantized models or multi-modal AI systems.
Bandwidth determines how fast data moves from VRAM to compute cores. Higher bandwidth reduces inference latency significantly. Look for PCIe 5.0 cards with high GB/s bandwidth ratings.
Cards with wider bus widths like 512-bit or 256-bit generally provide the throughput needed for large context windows.
Modern architectures like NVIDIA Blackwell or AMD RDNA 4 include dedicated AI accelerators. These cores speed up matrix multiplications which are common in LLM inference and fine-tuning.
Ensure the card supports FP8 or FP4 precision if you plan to use newer models optimized for lower bitrates.
Local AI workloads often sustain high utilization for hours. Passive or blower-style cooling helps in multi-GPU server racks while axial fans suit single GPU desktops.
Choose models with phase-change thermal pads or vapor chambers to maintain clock speeds under prolonged thermal stress.
High-end GPUs consume significant electricity. Verify your power supply unit meets wattage requirements especially for workstation cards rated near 600W.
Efficient power management helps reduce long-term costs and thermal output in compact builds.
NVIDIA CUDA remains the dominant standard for AI libraries. AMD and Intel offer ROCm and oneAPI alternatives but require more setup.
Check if your preferred LLM framework supports the card architecture before purchasing to avoid compatibility headaches.
Error Correcting Code memory prevents data corruption during long training runs. This is essential for enterprise environments where data integrity is paramount.
Look for workstation cards specifically listing ECC support if you need maximum reliability for scientific computing.
Scaling across multiple cards increases total VRAM capacity. Ensure the card supports PCIe peer-to-peer communication for efficient multi-GPU communication.
Desktop cases must accommodate physical spacing between cards to prevent thermal throttling when stacking units.
Start by installing the latest drivers from the manufacturer website and ensure your operating system supports the GPU architecture properly.
Use software tools like NVIDIA System Management Interface to monitor temperatures and memory usage during model inference tasks regularly.
Clean dust from cooling vents monthly and maintain consistent case airflow to prevent hardware degradation during intensive AI workloads.
For most open-source models you need at least 16GB VRAM to run quantized versions. Larger unquantized models require 32GB or more. If you want to fine-tune models consider 48GB or higher.
Yes NVIDIA CUDA support remains the most mature ecosystem for AI development. However AMD and Intel offer competitive hardware at lower prices for specific workloads.
Absolutely. Gaming cards with enough VRAM handle inference well. Just ensure drivers are updated and thermal design supports sustained loads without throttling.
GDDR7 offers significantly higher bandwidth and efficiency than GDDR6. This reduces data transfer bottlenecks during inference and improves model response times.
ECC memory is vital for enterprise reliability to prevent data corruption during long training. For casual inference non-ECC consumer cards work fine.
Check the card specs for recommended PSU wattage and power connector types. Ensure your unit has enough PCIe power connectors to meet demands safely.
Multi-Instance GPU lets you split one GPU into multiple isolated virtual units. This allows secure simultaneous execution of different AI workloads or users.
PCIe 5.0 doubles bandwidth over Gen 4 which helps data transfer for large models. It is future-proofing for multi-GPU clusters but not strictly necessary for single card inference.
The top picks cover a range of needs from budget-friendly experimentation to enterprise-grade deployment. The ASUS Turbo Radeon and NVIDIA RTX PRO cards lead in raw capacity.
Prioritize VRAM capacity and bandwidth if your primary use case is hosting large unquantized models. Otherwise gaming cards offer surprising performance for quantized workloads.
Prices fluctuate frequently so check current listings for availability before you decide. Select the card that fits your model requirements and workstation constraints.